Data Flows is a visual tool within the Zeta Marketing Platform (ZMP) that can ingest and integrate any data source, either one-time or as an ongoing feed. With Data Flows, you can seamlessly manage data workflows and conduct master data management tasks like cleansing, accuracy checks, resolving duplicates, and flexible extract, transform, and load (ETL) functions through a straightforward, low-code user interface. Furthermore, use this powerful feature to:
-
Accelerate the speed of data integration and onboarding to drive timelier customer engagement
-
Minimize or eliminate the need for technical intervention to manage your own data on your own terms
-
Harmonize your data so that your systems are connected and speaking the same language
-
Simplify your data operations and gain complete transparency into your most valuable asset—your customer data
Navigation
From the menu on the left, navigate to Data > Data Flows. Click on New Data Flow to open the canvas.
ZMP data flows are currently comprised of these three 3 components: Source, Destination, and Action.
|
Source of Data (required) |
Destination of Data (required) |
Actions on the Data (optional) |
|---|---|---|
|
This is where you will be pulling the data from. |
This is where you will be sending the data to. |
These are various actions that can be taken on the data to ensure that the data has everything it needs for use by the destination of the data. |
|
Everyone to have access to all sources |
Everyone to have access to all sources |
Some Data Actions will be restricted to certain accounts if built custom for the client, or if those actions require payment. |
|
Types of Sources
|
Types of Destinations
|
Available Actions (changes often)
|
Selecting the Source
1. Click on Add Source.
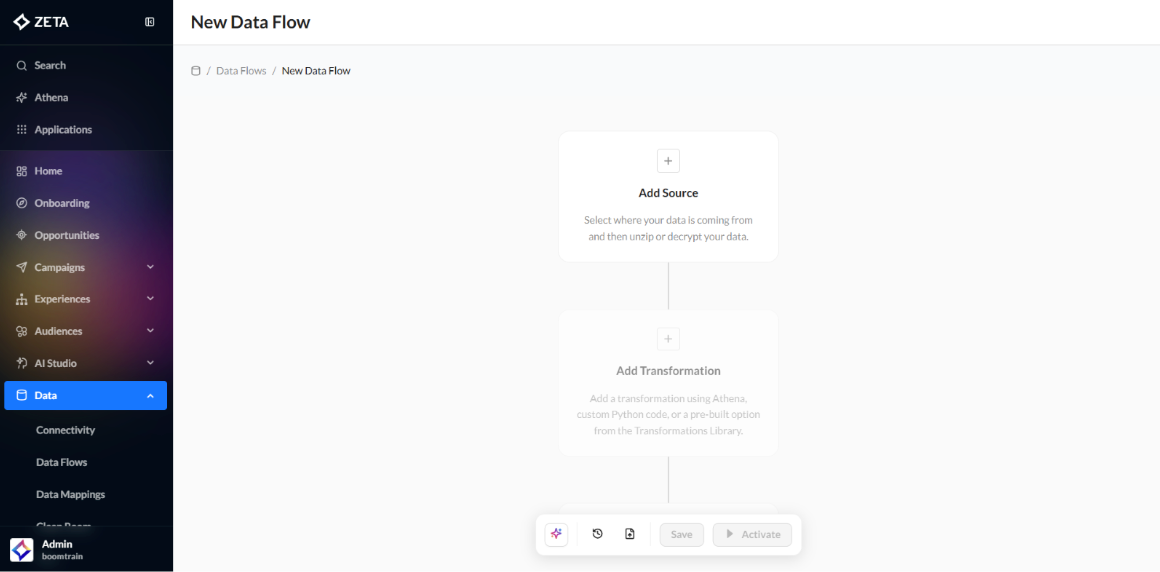
2. Choose your desired option from the connector tiles.
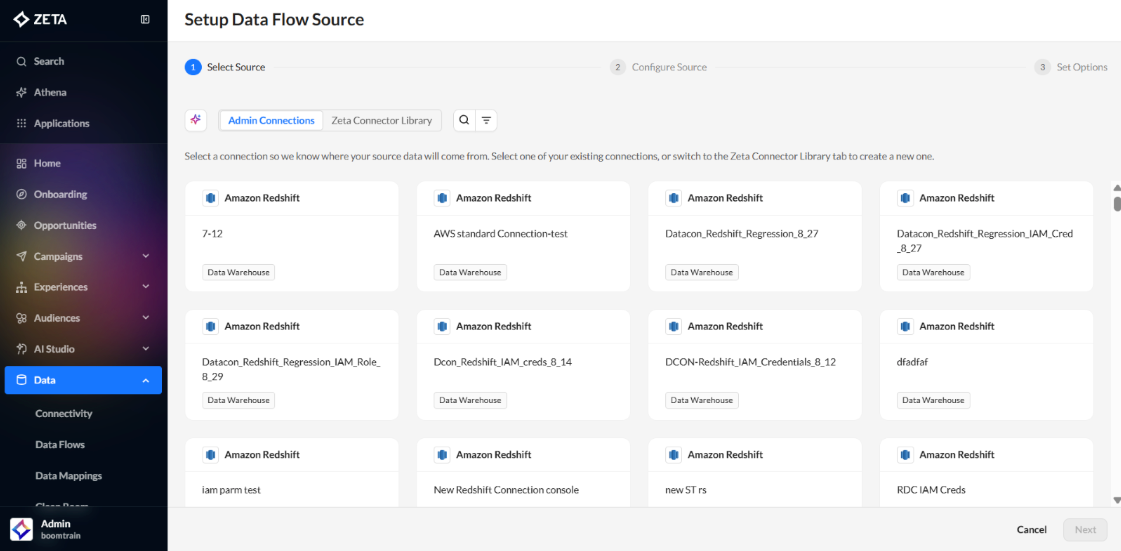
3. Click on Next to set up your connection, then review it.
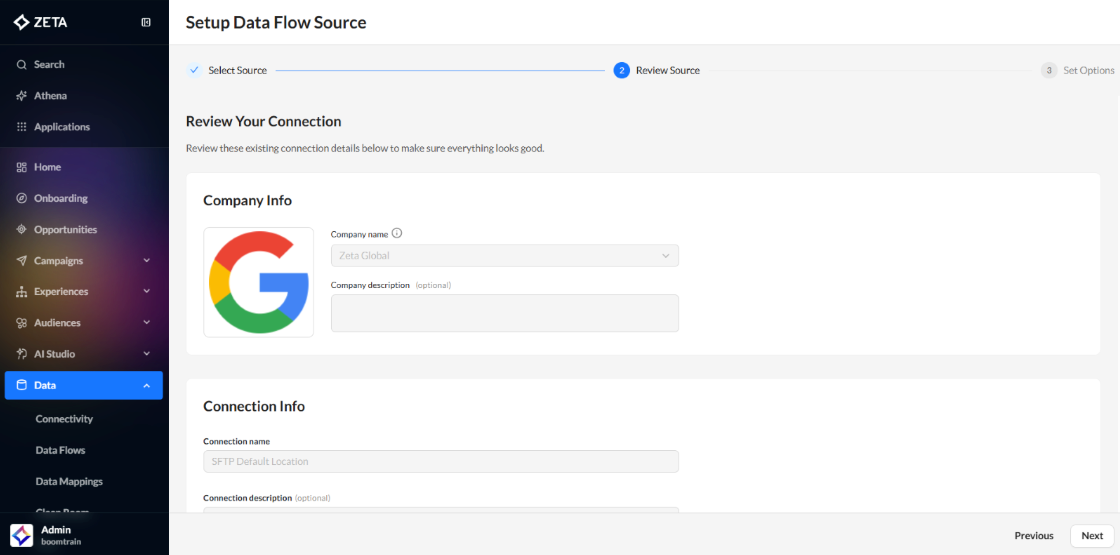
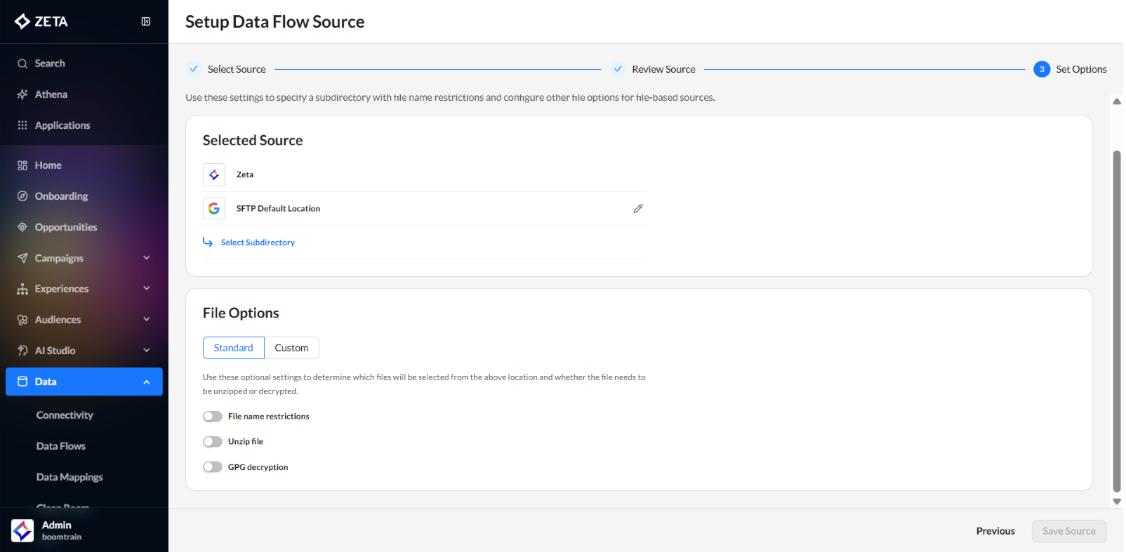
-
Add your ideal file options for your selected source, and click Save Source.
Click here to see how the Amazon S3 Buckets, Google Buckets, Microsoft Azure Blob Storage, and External SFTP can be configured for self-serve connection management.
Any queries created for either Snowflake or BigQuery from within Data Flows can only be used in those flows. Query Segments created from the Segments and Lists page can be used in Data Flows as well.
Encrypted files can be decrypted in the Source card using a dropdown of private keys from Settings > Keys. Outgoing files can be encrypted in the Destination card using a dropdown of public keys from Settings > Keys.
Deciding the Action
Adding a Transformation
Once you have added the source to the canvas, click the Add Transformation button to open the Transformations Library.
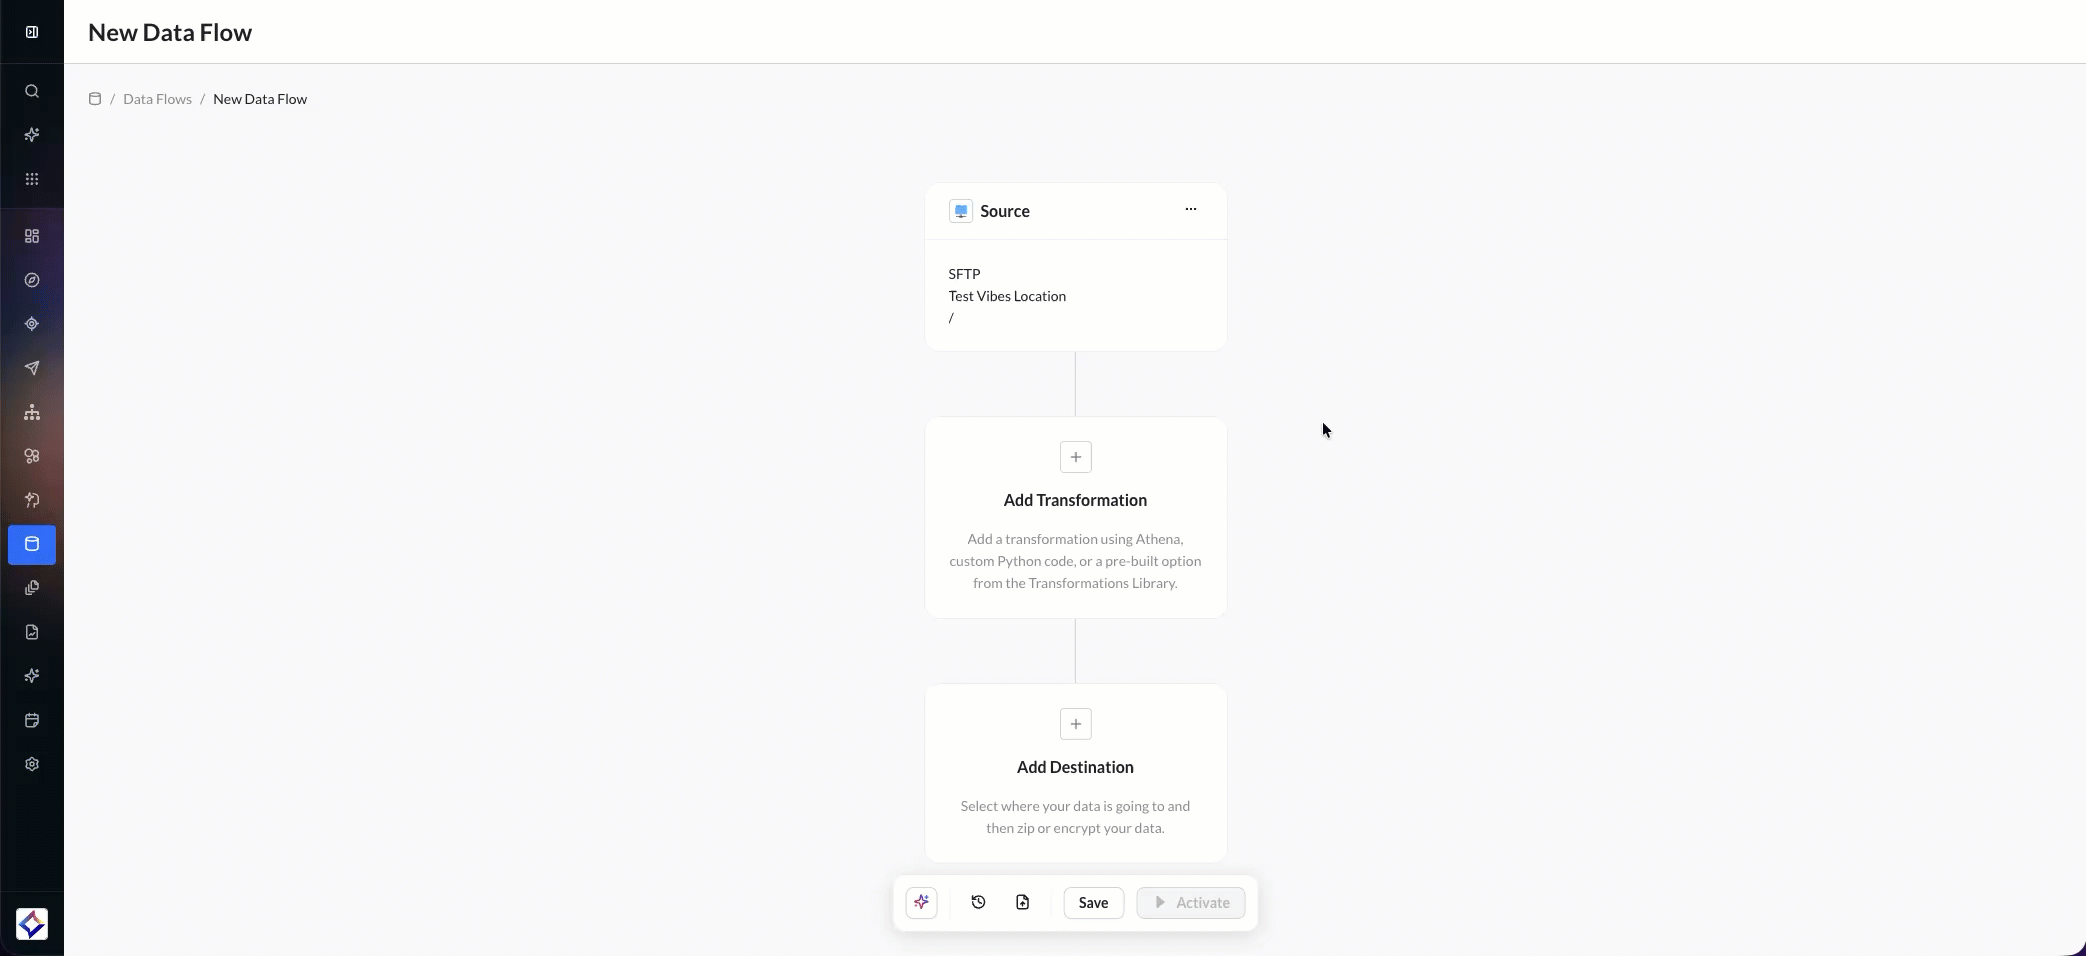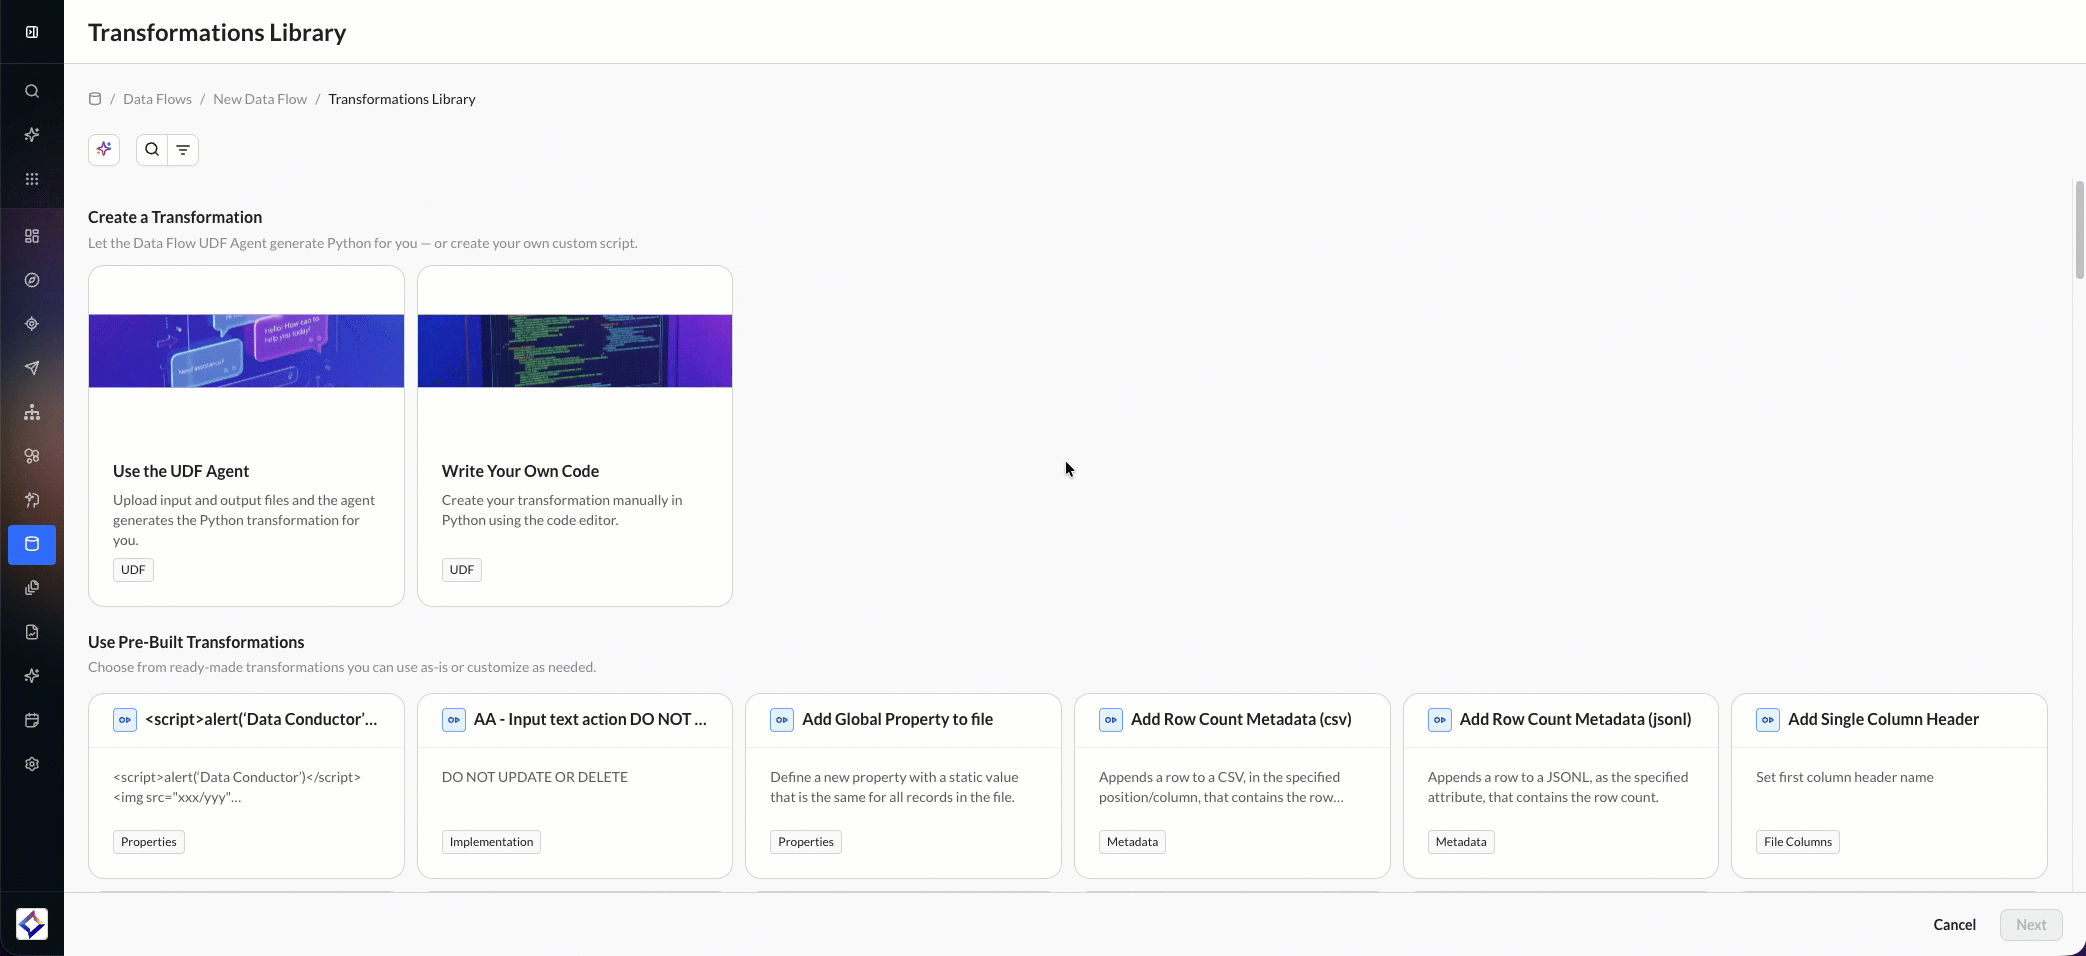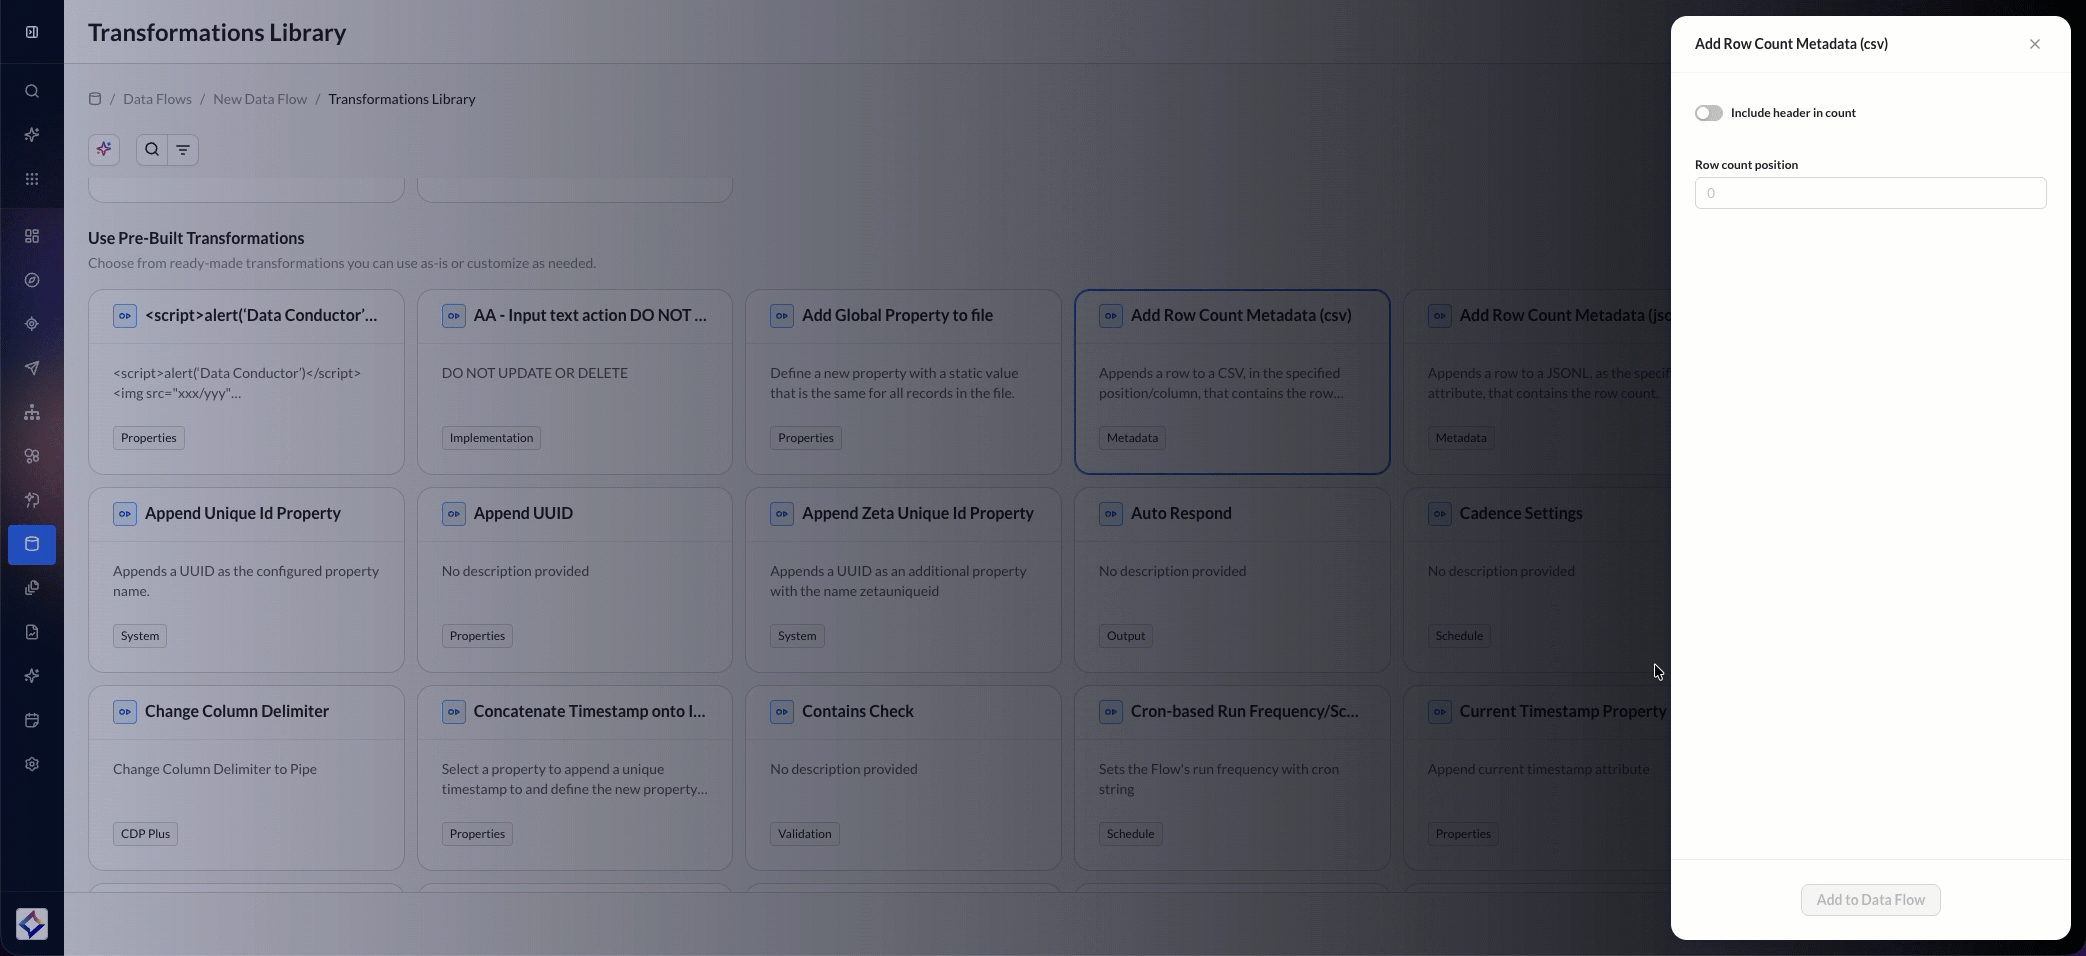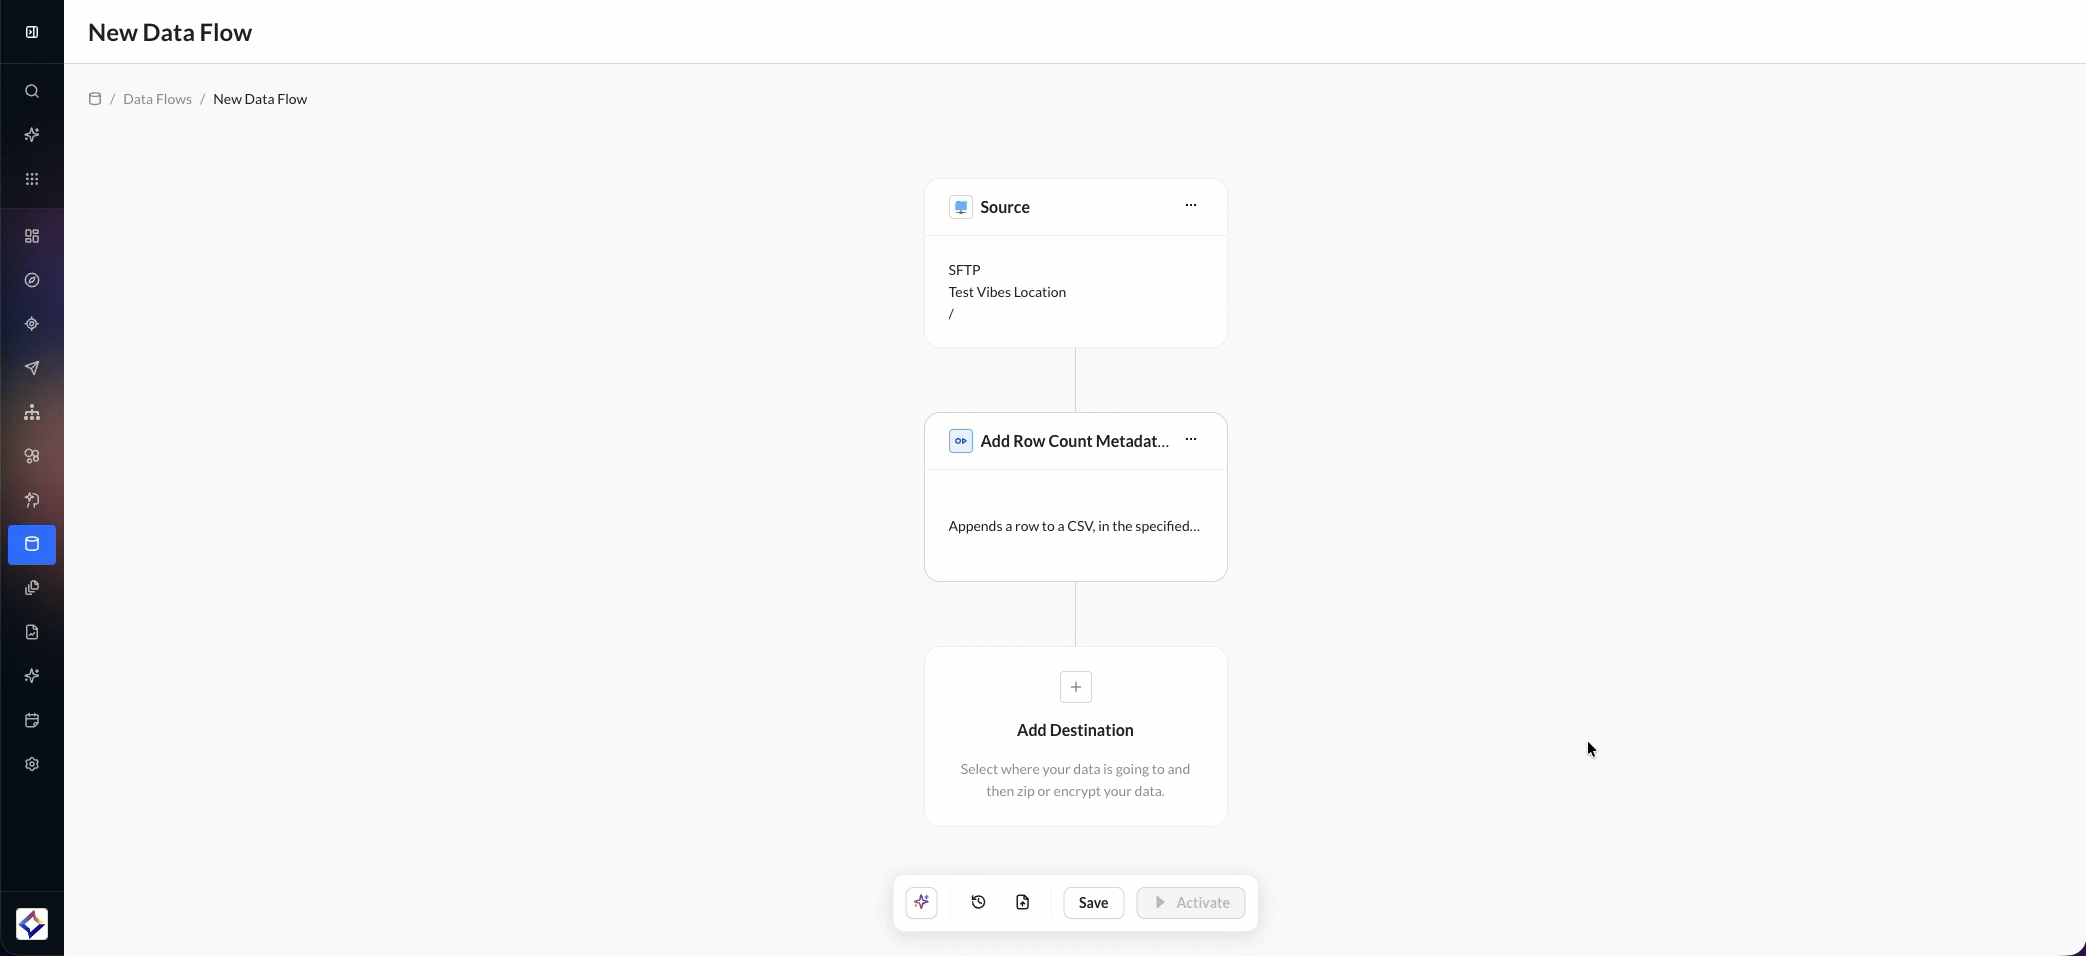
Use it to add prebuilt Action Nodes, create a UDF with the UDF Agent, write your own Python (UDF), or reuse an existing mapping.
The library is a full page, not a modal. The breadcrumb is Data Flows / [flow name] / Transformations Library.
On the Transformations tab:
Use a Pre-Built Transformation:
1. Select a card in the prebuilt grid.
2. A drawer opens on the right with that node’s settings. This is not a modal.
3. Configure the node, then click Add to Data Flow. To leave without adding it, close the drawer.
When you edit a node already on the canvas, the same drawer opens and the primary button is Save.
Create a Transformation:
Use the UDF Agent and Write Your Own Code to open a full-page editor, not the drawer. See UDF Agent and Custom Python Transformation (UDF).
After a transformation is on the canvas, click + on either side of that node to insert another one.
On a canvas card:
-
Click the card to edit it.
-
Use ⋯ for Edit, Edit Code (UDF), Settings (UDF), or Delete.
-
Delete asks you to confirm Delete transformation?
A Data Flow can include one UDF: either the UDF Agent or Write Your Own Code. After one is added, the other option is hidden or disabled in the library, with a tooltip explaining the limit. Remove the UDF to choose a different type. This does not apply to Output File Format.
For the catalog of prebuilt nodes, see Data Flow | Action Nodes.
A Data Flow can include one UDF node: either Use the UDF Agent or Write Your Own Code. After one is added, the other option is hidden or disabled in the Transformations Library. Remove the UDF from the canvas to choose a different type. This limit does not apply to Output File Format or to prebuilt Action Nodes. You can still add multiple prebuilt nodes around the UDF.
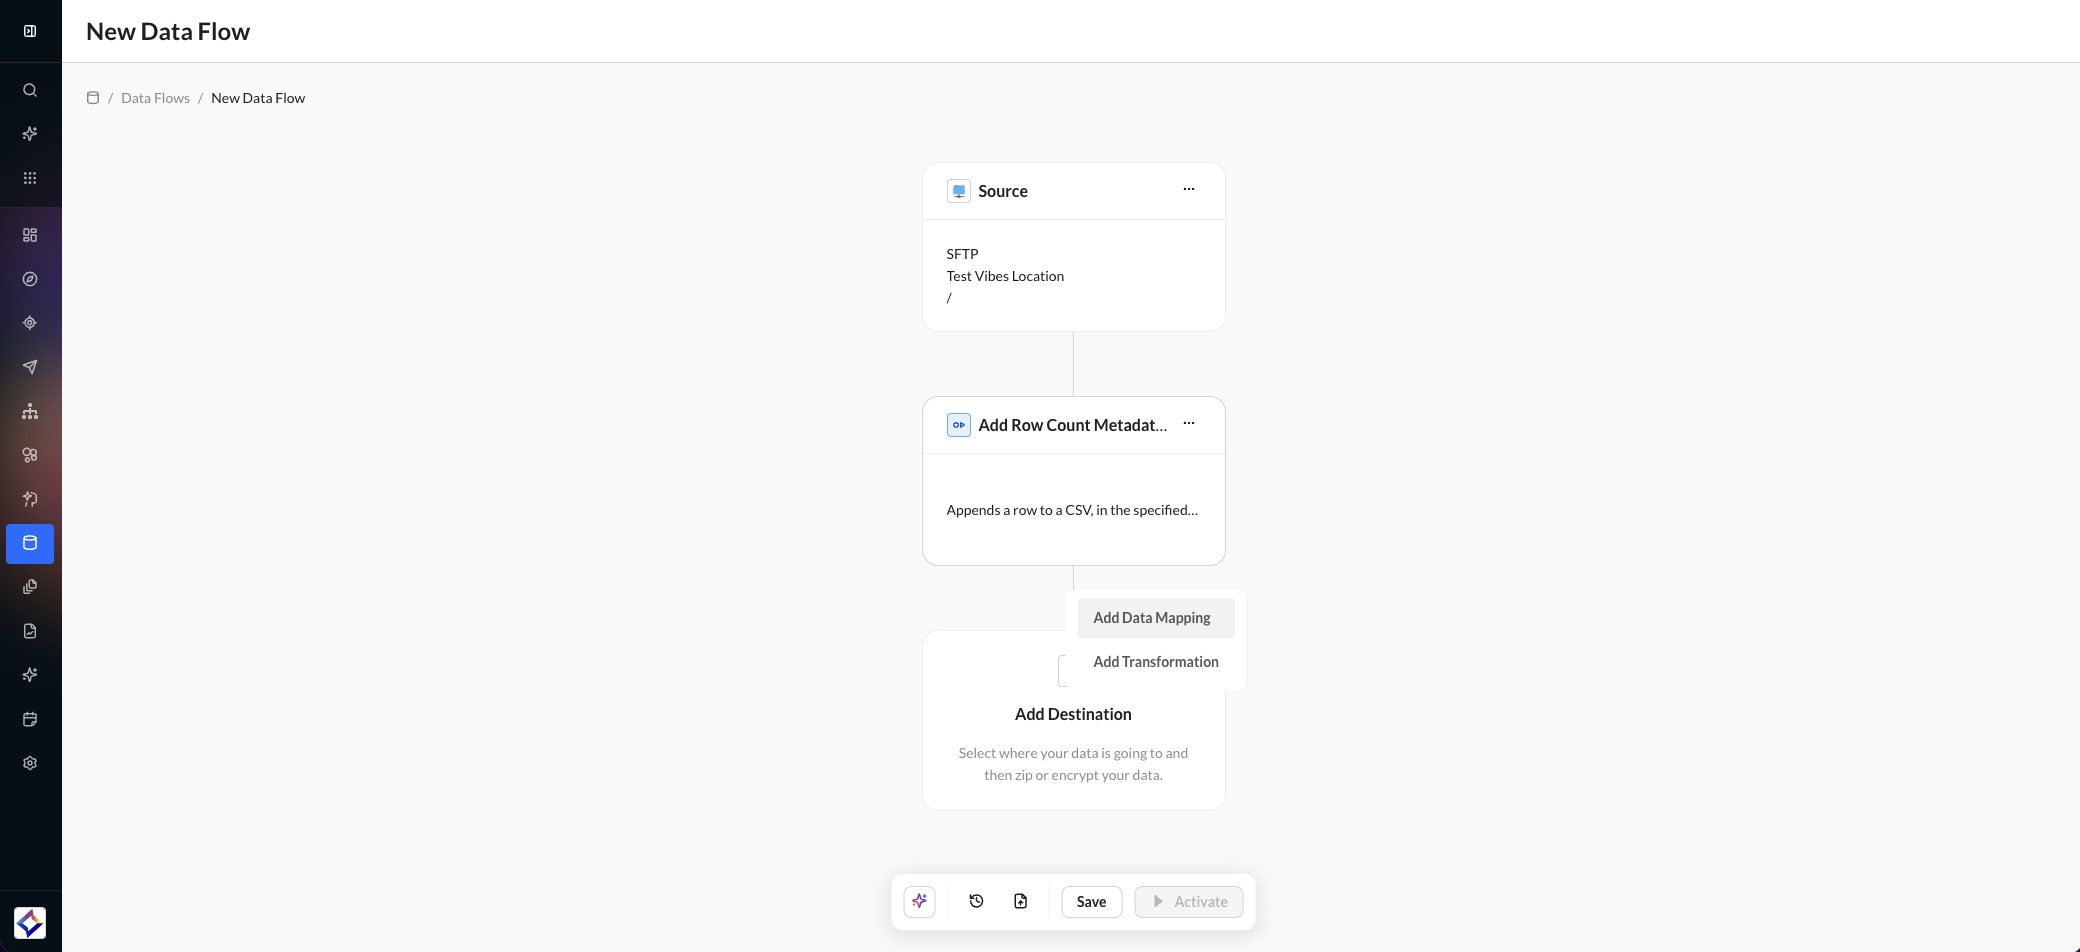
Adding a Data Mapping
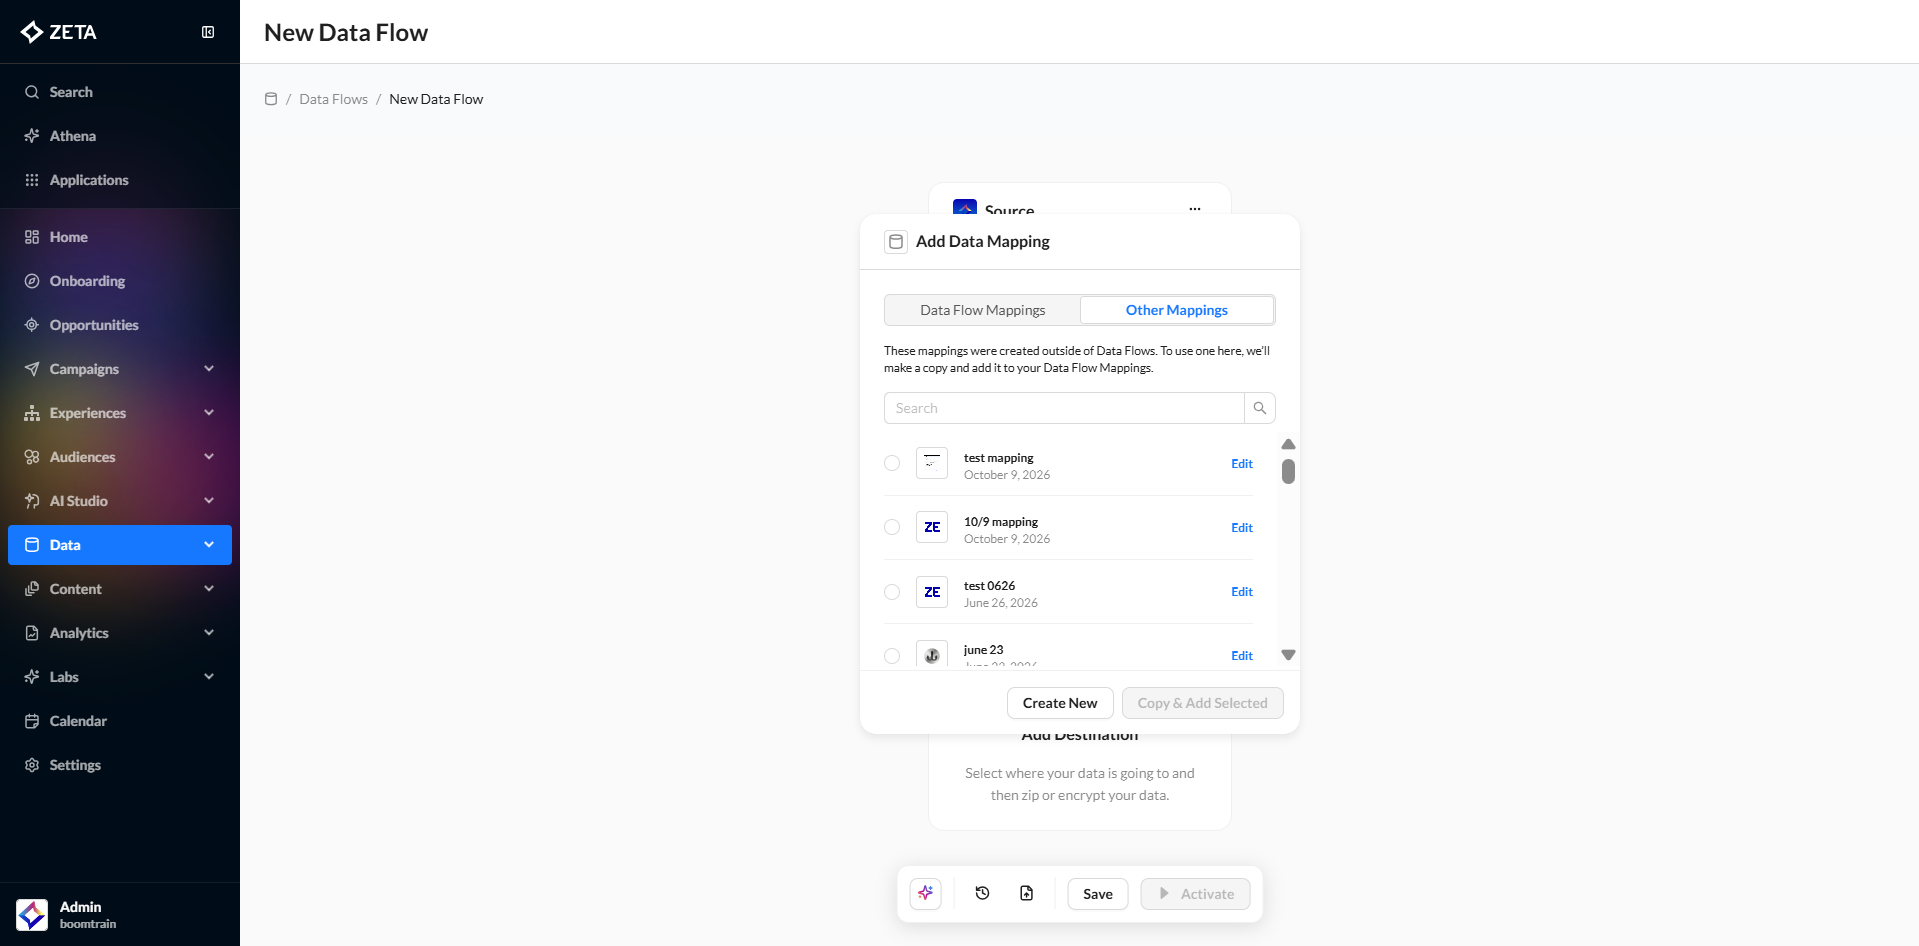
After you have added a transformation, you can either add another transformation or add a data mapping. Click Add Data Mapping. Pick a saved mapping (see Data Mappings), or create one for this flow. Review the column mappings, then add it to the canvas.
A Data Flow can include one mapping. You can remove it and add a different one.
Choosing the Destination
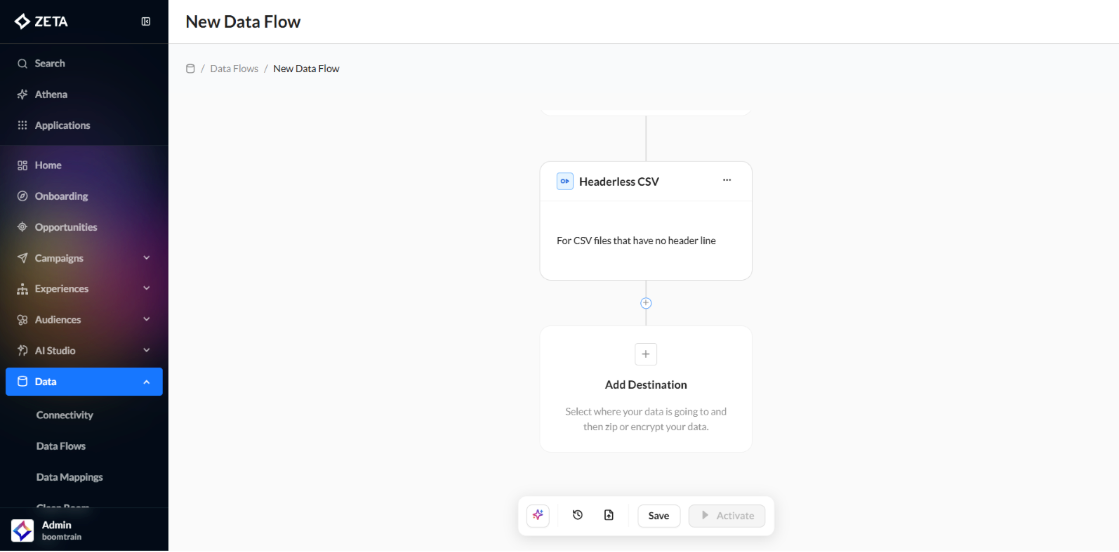
1. After you’ve selected the data actions, click on the Add Destination button to select a destination from the list.
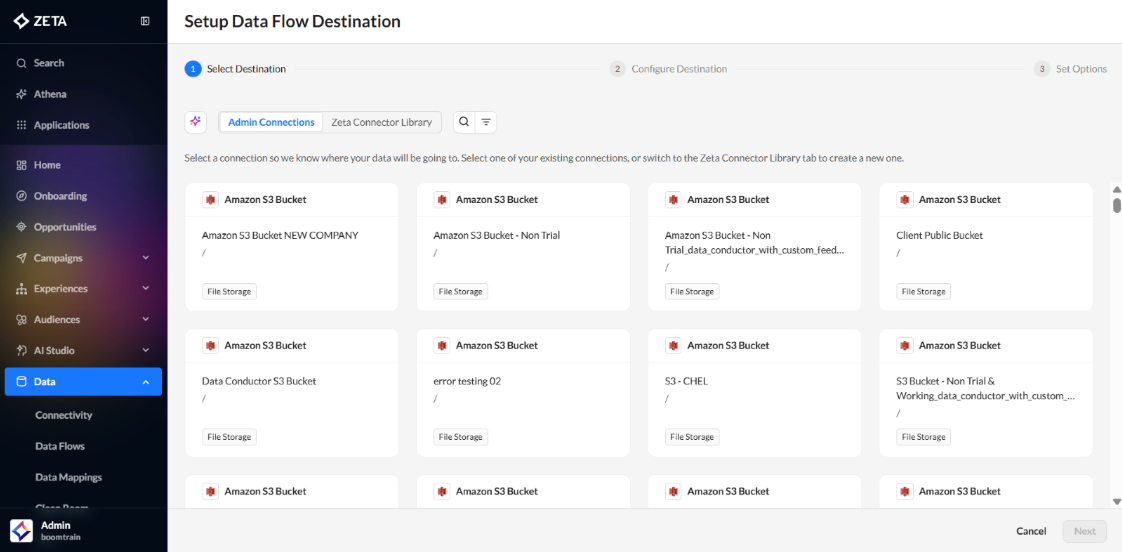
2. Choose your desired option from the connector tiles.
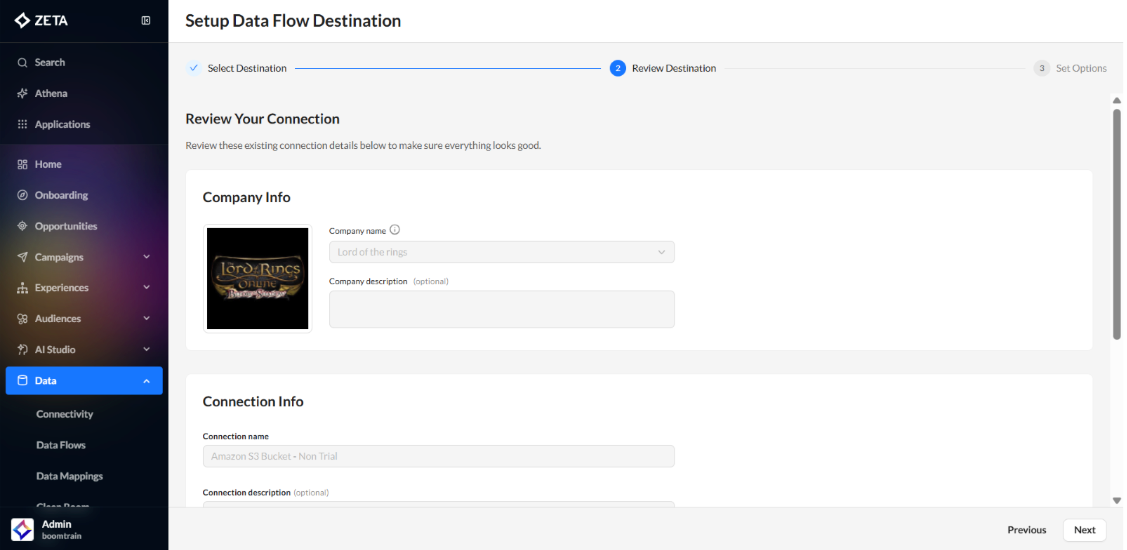
3. Click on Next to set up your connection, then review it.
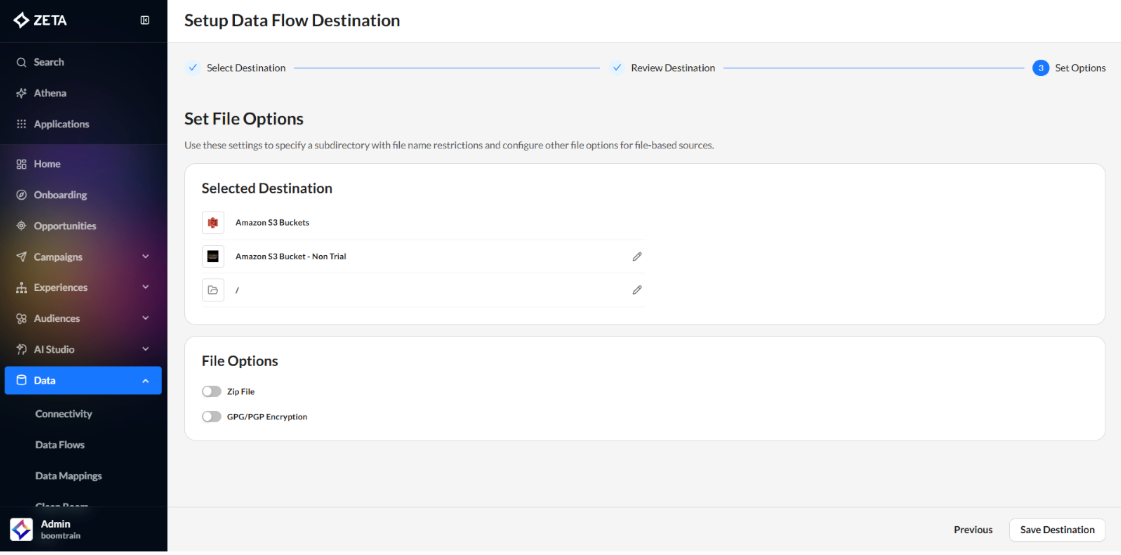
-
Add your ideal file options for your selected destination, and click Save Destination.
Visualize Output Data
After the source, mapping or transformation, and destination are on the canvas, the flow is shown as connected cards.
1. Review the path.
2. Use the segmented control in the top-right to switch between horizontal and vertical layout. Use the mini-map in the bottom-left to pan and zoom.
3. Click a card to edit it, or use ⋯ on the card.
4. Click Save in the top-right.
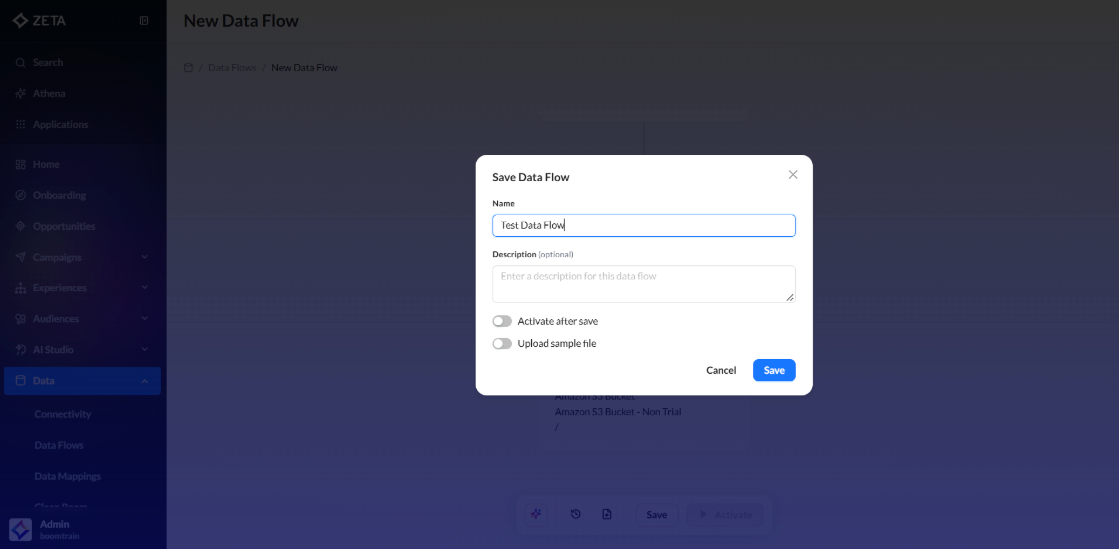
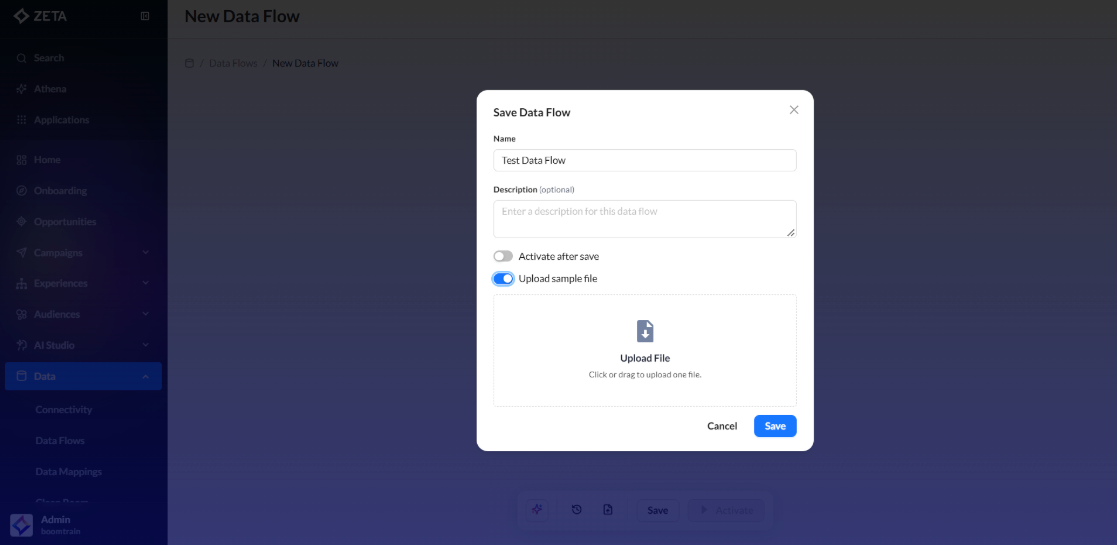
-
The data flow canvas is not editable if you chose Activate after save. Deactivate the flow before you edit it.
-
If you chose Upload sample file after save only, the data flow stays editable in a Draft state. Click Save / Activate when you are ready.
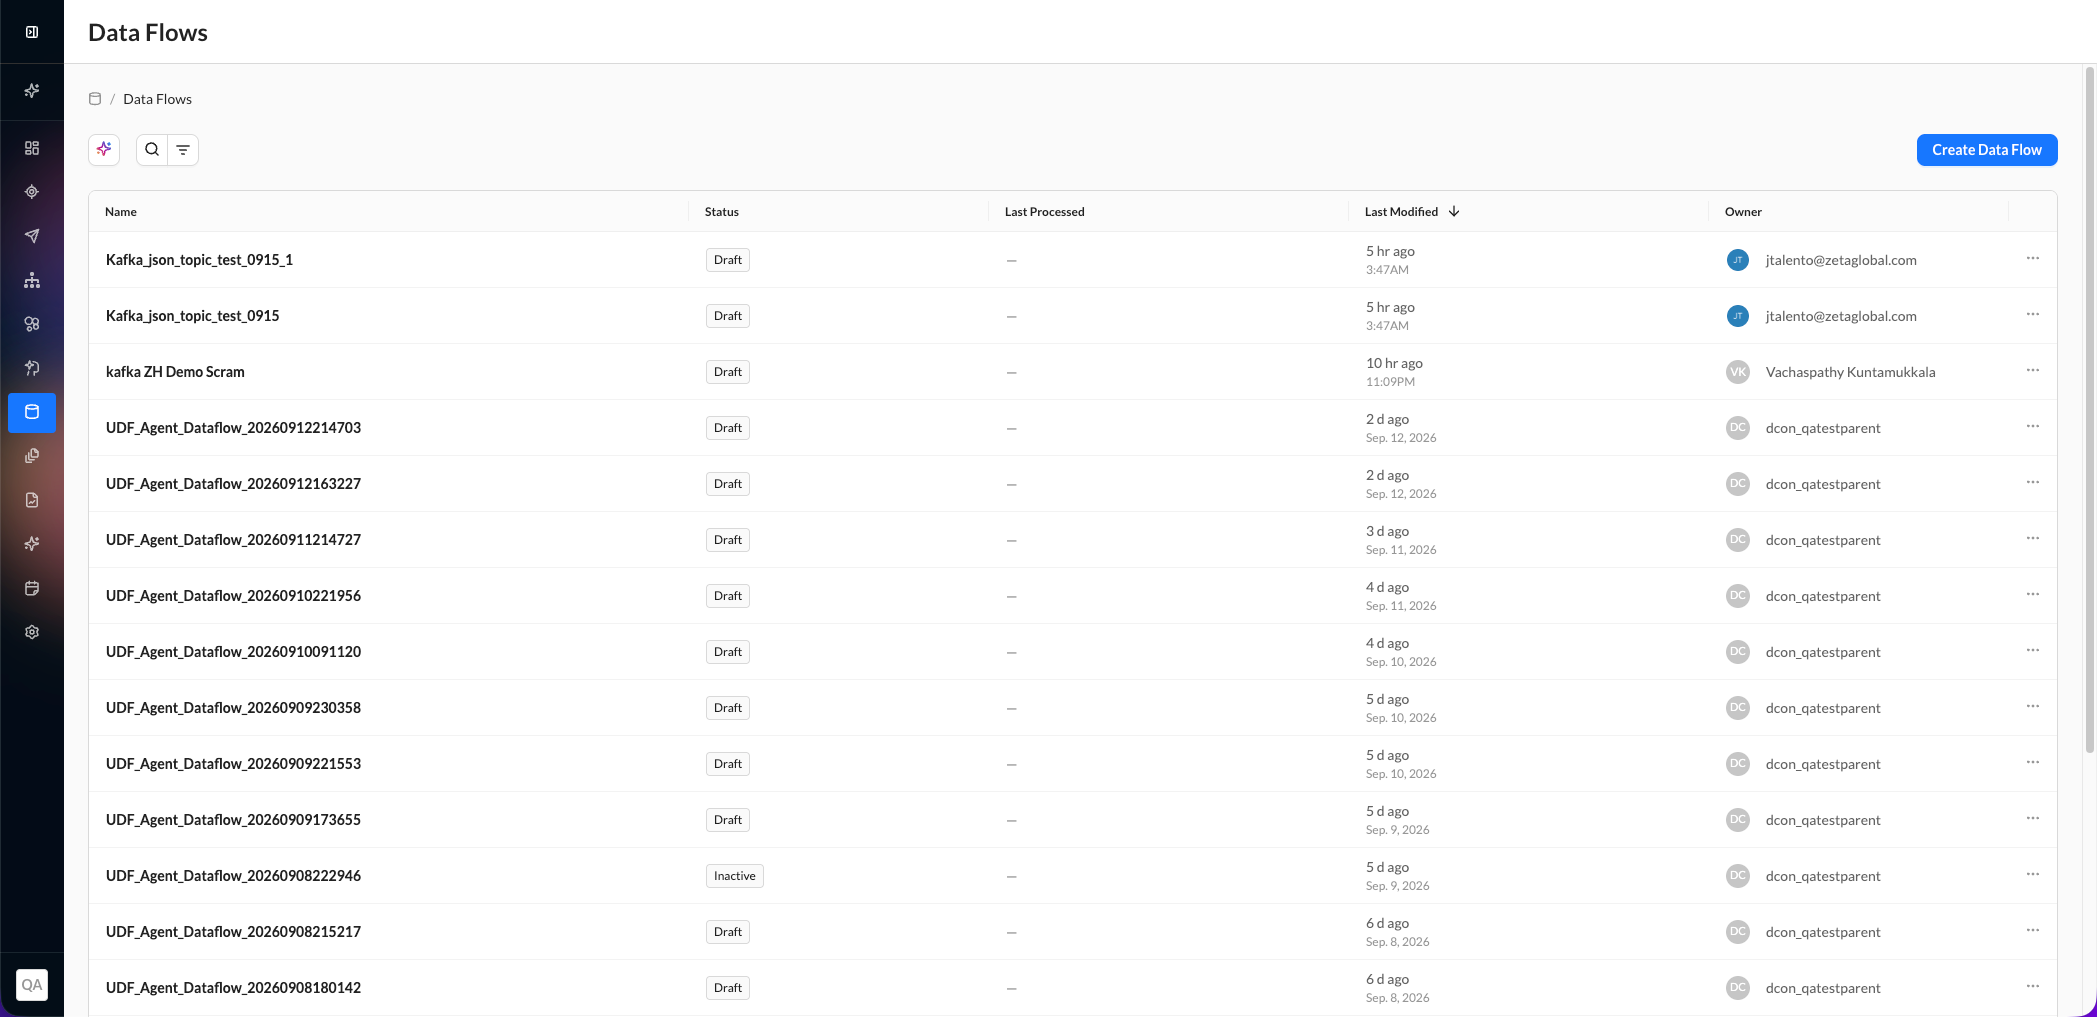
-
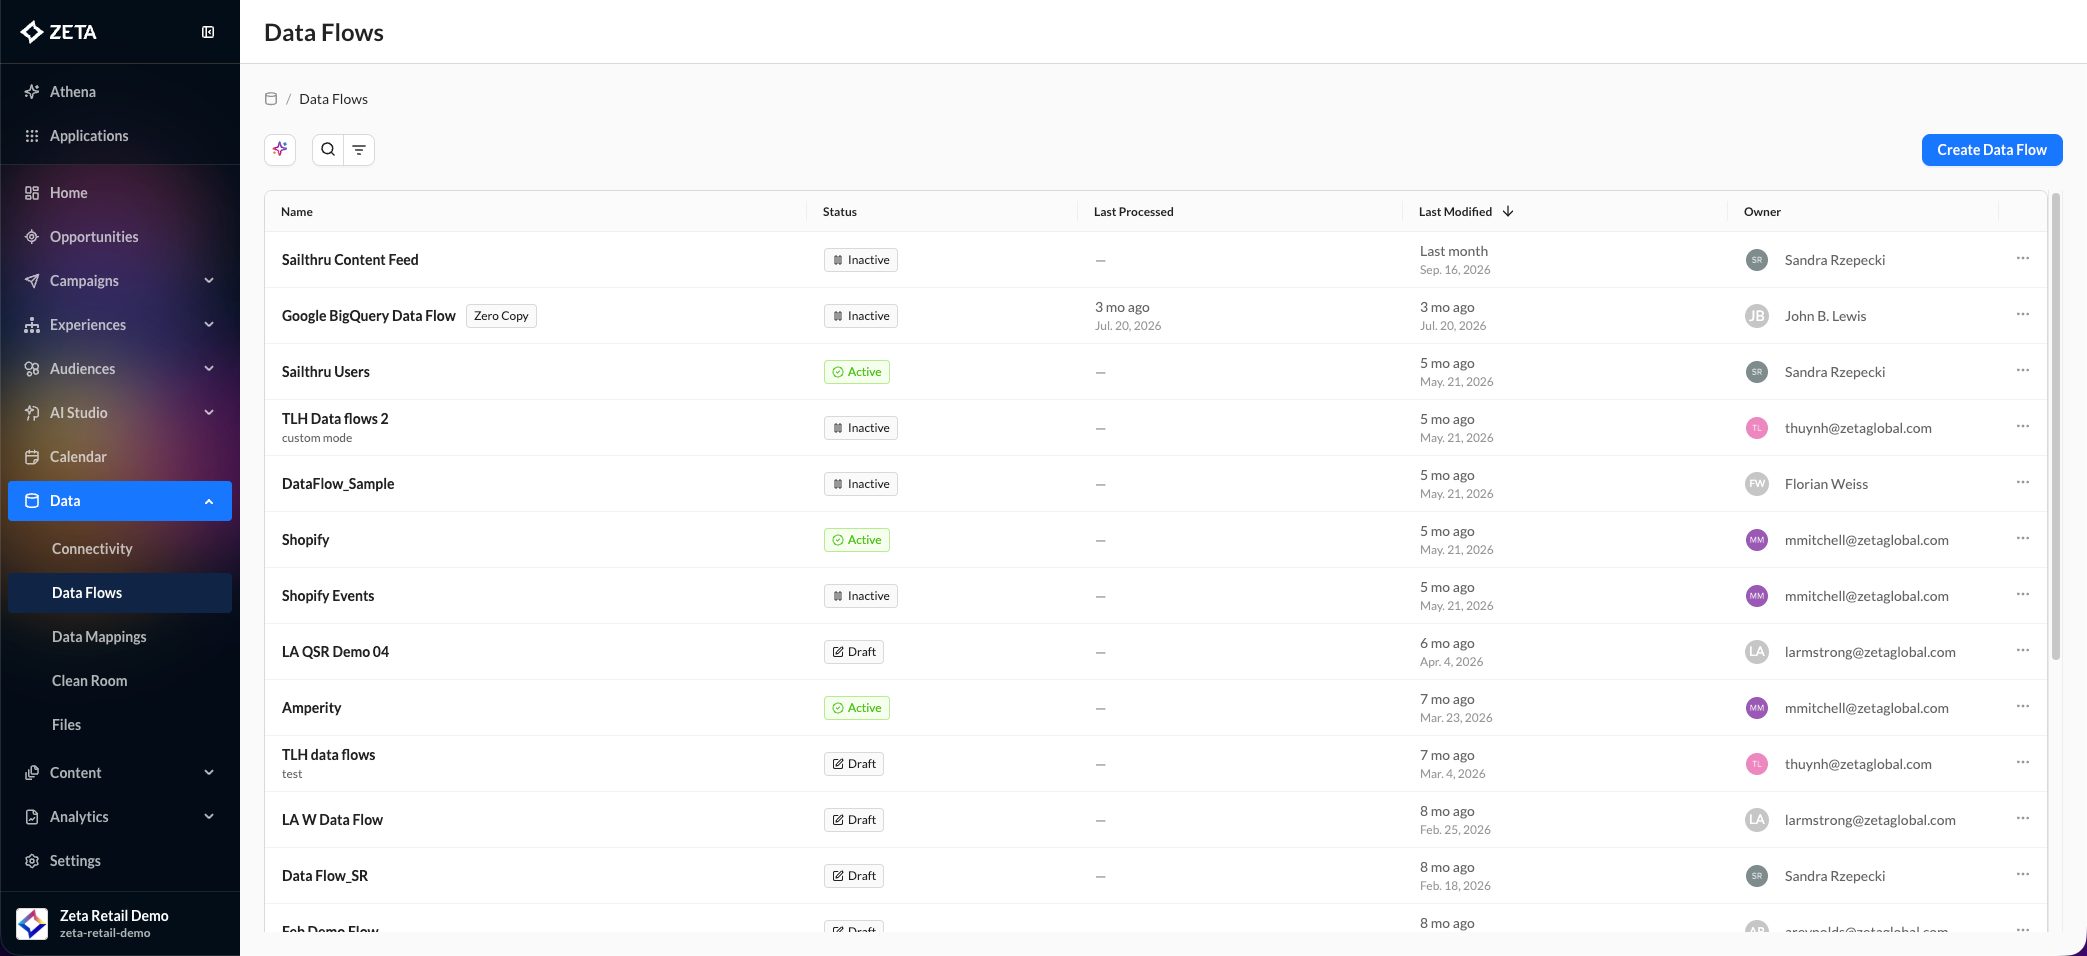
The data flow list view shows the status of the flow. Open the flow to return to the canvas.
|
For Snowflake and Google BigQuery sources, you can choose whether the flow runs immediately on activation or only on the schedule in the source card. By default, the toggle is on, so the flow runs immediately on activation (backward compatible). This option appears when you activate a flow for the first time (save modal or the options menu next to the data flow name) and when you reactivate a deactivated flow. To enable this option in your accounts, contact Zeta Support. It is not generally available. |
View Data Flows
You can view the data flow running once the source, transformation, and destination have been added.
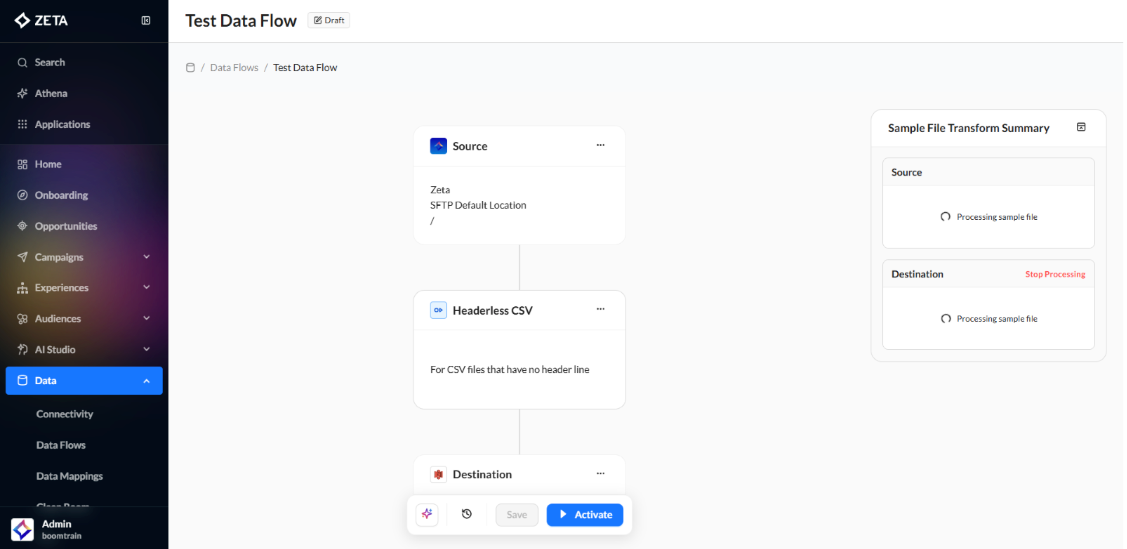
You can upload a sample file from the canvas. You do not need to save the flow or choose a destination first.
Allowed file types for the canvas sample are CSV and JSONL.
Based on the sample:
-
the action cards are stacked,
-
a source summary appears at the top-right, and
-
if a destination is already on the canvas, that card shows that the data is being processed.
Data Flow State Change Notifications
Email notifications are sent out under the following scenarios:
-
Data Flow is Activated
-
Data Flow is Deactivated
-
Data Flow is Shared from one account to another
-
Data Flow is requested to be approved
-
Data Flow is Approved
-
Data Flow is Rejected
In all these cases, users who are on the ZMP notification list will receive these emails, as well as users whose emails were added in the Notifications or Approval steps when a data flow is shared.
Users who do not want to receive these emails will be able to remove themselves and even add back on in the future if their needs change.
Occurrence History
Data Flow Occurrence History provides a running real-time list of all executions that are in progress or have happened in the past.
From the data flows list view, click on the action menu against the data flow and click on Occurrence History.

-
The flow could be Running, Completed with Success, or Completed with failure.
-
A list of metrics, such as input file name, row count, etc., will also be displayed.
-
There is also a badge that shows up when a data flow fails. The badge remains till the next 10 runs execute successfully, at which point it clears up. The badge is clickable, and upon clicking navigates the user automatically to the newest error.

You can also use the search or add filters for dates or statuses to further refine your results